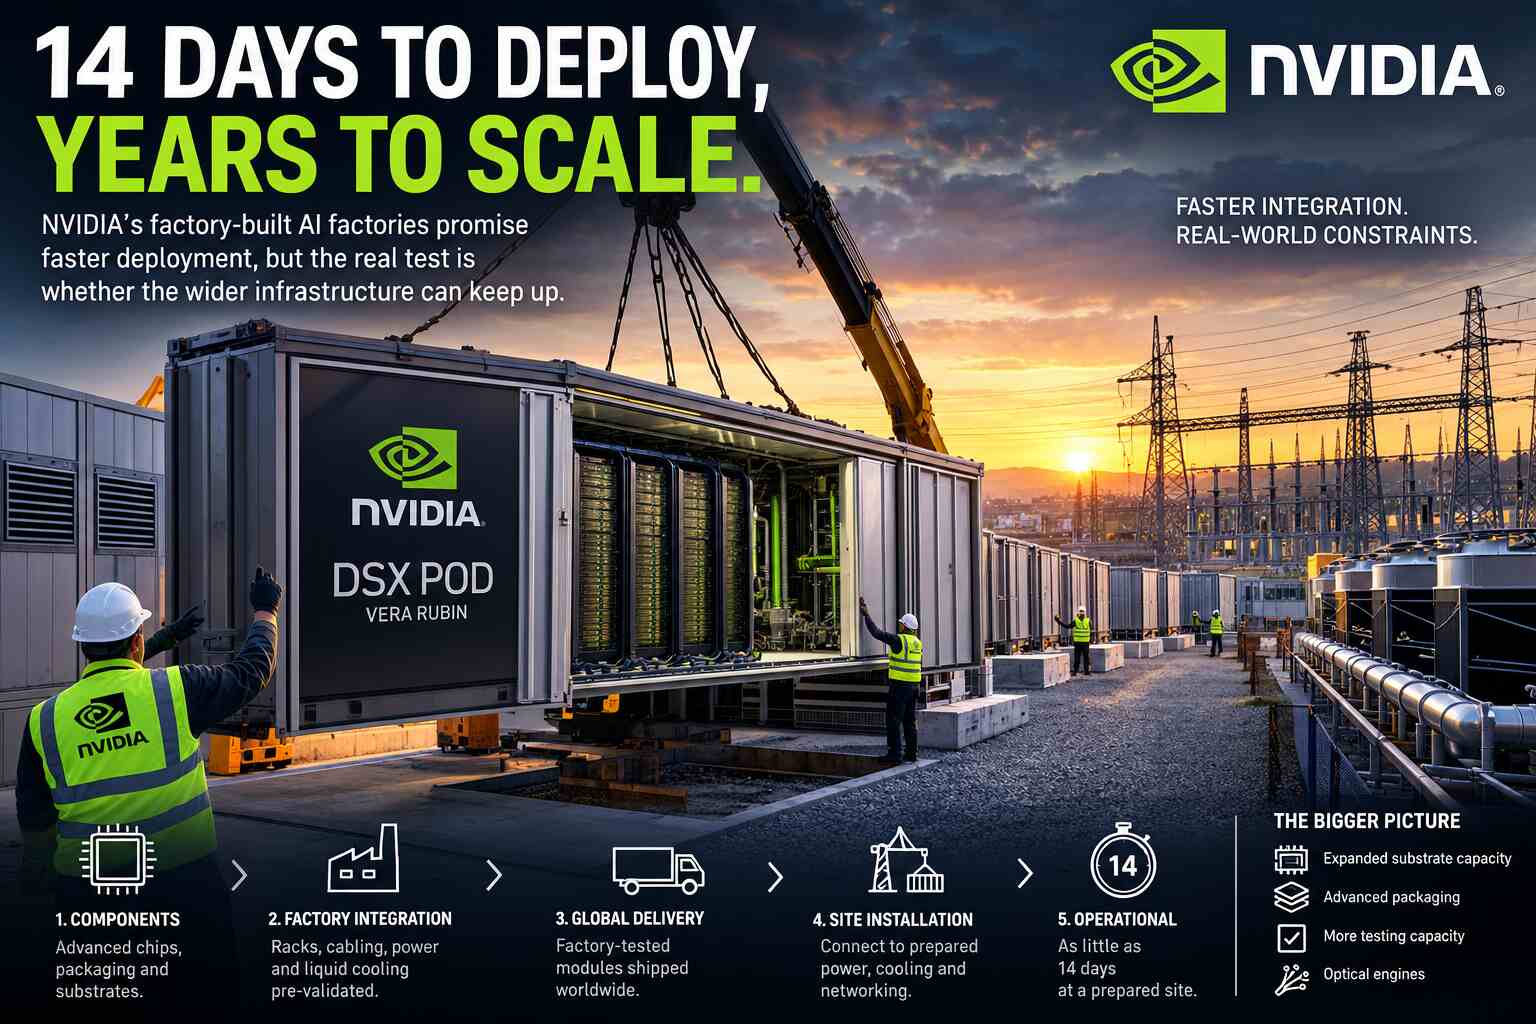
NVIDIA is taking on a broader role in the artificial intelligence infrastructure market, shifting from a primary supplier of processing units to an architect of standardized, factory-integrated computing solutions. Through the introduction of the DSX POD reference design at GTC Berlin, the company aims to streamline the deployment of AI supercomputers, potentially reducing installation timelines at prepared sites from six months to fourteen days. Furthermore, by concurrently announcing strategic supply-chain investments in semiconductor substrates, advanced packaging, testing, and optical engines, NVIDIA is working to accelerate the entire lifecycle from manufacturing to operational output. While these initiatives offer a repeatable framework for infrastructure development, the industry must still navigate the persistent tension between the rapid assembly of computing hardware and the external dependencies, such as grid capacity and site readiness, that remain critical to project success.
“We are in the midst of the largest infrastructure buildout in human history. Demand is extraordinary. Capacity is the constraint,” said Jensen Huang, founder and CEO of NVIDIA. “Our supply chain partners are the world’s best manufacturers. I’m grateful they are expanding capacity around the globe to scale production and help us deliver the AI supercomputing systems powering this new industrial revolution.”
From GPU systems to factory-built AI infrastructure
NVIDIA’s DSX POD concept shifts substantial integration work away from the customer’s data center and into a controlled manufacturing environment. Participating partners assemble the computing systems, complete rack-to-rack cabling, install wiring and piping, and conduct functional validation before the modules are shipped.
The delivered units are designed to connect to a prepared site’s power, cooling, networking, and supporting infrastructure. Instead of coordinating every stage of rack installation and system integration at the destination, operators can perform much of that work in parallel with site preparation.
NVIDIA is working with a broad ecosystem of manufacturers and infrastructure companies, including Dell Technologies, Hewlett Packard Enterprise, Lenovo, Foxconn’s Ingrasys operation, Bull, Quanta Cloud Technology, Schneider Electric, Vertiv, Eaton, and others. Worldwide deliveries are planned to begin in early 2027.
This is more than a packaging change. It represents an attempt to make large-scale AI computing deployments resemble a repeatable industrial production process rather than a series of bespoke data center projects.
For high-performance computing operators, standardization could reduce integration variability, simplify validation, and make it easier to plan capacity additions. Factory testing may also identify configuration problems before equipment reaches an operational facility, where troubleshooting can be more expensive and disruptive.
However, DSX POD is a reference design delivered through NVIDIA’s partners, not a turnkey data center that NVIDIA independently constructs from the ground up. The distinction matters: manufacturing, transportation, site readiness, commissioning, and operational support remain distributed across the supply chain.
The 14-day promise begins where the hardest infrastructure work may already be finished
NVIDIA’s headline deployment claim requires careful interpretation.
The company compares a conventional deployment period of approximately six months with a target of as little as 14 days at a prepared site. The shorter interval benefits from moving integration and validation into the factory and reducing the amount of work required after delivery.
But the clock does not encompass the entire process of establishing an AI data center.
Land acquisition, permitting, civil engineering, grid connections, electricity procurement, facility construction, and transportation are not eliminated by preassembling computing infrastructure. Nor does a standardized module guarantee that every destination has sufficient electrical capacity, cooling performance, network connectivity, or space for the intended deployment.
These constraints have become increasingly consequential as AI infrastructure grows from individual server installations into facilities demanding hundreds of megawatts or more.
A containerized system can arrive ready for connection, but it cannot manufacture a missing grid connection. Factory validation can reduce integration risk, but it cannot resolve a local permitting dispute or guarantee that the required power is available when the equipment arrives.
The distinction between installation time and total project delivery time should therefore remain central to evaluating NVIDIA’s claim.
For operators with prepared sites and established infrastructure, the approach could substantially shorten the path to productive compute. For projects still waiting on substations, transmission upgrades, or construction approvals, the benefits may be limited by the slowest unresolved dependency.
NVIDIA is also investing in the supply chain behind the factory
The DSX POD announcement is only one part of the strategy. NVIDIA’s accompanying supply-chain plans target manufacturing capabilities that help determine how quickly advanced computing systems can be produced in volume.
The company identified agreements and expansion plans involving six partners:
- IBIDEN: An expansion of substrate capacity at its Ono Plant in Japan, with additional capacity expected to begin ramping in the first quarter of 2028.
- Samsung Electro-Mechanics: Additional substrate supply from existing South Korean operations, alongside planned upgrades and new facilities.
- Unimicron: Expanded substrate capacity, with additional capacity targeted for the second quarter of 2027 and full capacity expected around mid-2028.
- Amkor Technology: Plans to increase advanced packaging capacity by more than 300% by the end of 2028.
- King Yuan Electronics, or KYEC: New U.S. testing facilities supported by a $1.1 billion capacity-reservation advance from NVIDIA, with high-volume production targeted for April 2027.
- Siliconware Precision Industries, or SPIL: A target to expand optical-engine capacity for co-packaged optics by 15 times by mid-2027, with a further doubling targeted by the end of 2028.
NVIDIA also outlined an aggregate target to increase substrate capacity 2.5-fold over three years through these and other initiatives.
The commitments address important stages of the manufacturing chain. Substrates provide the physical and electrical foundation for advanced semiconductor packages. Advanced packaging enables increasingly complex integration of computing components. Testing capacity is necessary to validate manufactured devices, while optical engines support high-bandwidth data movement within and between computing systems.
These capabilities are important because an AI supercomputer is not simply a collection of powerful processors. Its performance depends on the coordinated operation of compute, memory, interconnects, networking, storage, power delivery, cooling, and software.
A shortage in one critical component can delay the delivery of an otherwise complete system.
Yet the announcements should not be interpreted as proof that the semiconductor supply chain has been fully secured. Several targets extend through 2028, some financial commitments remain undisclosed, and the $1.1 billion KYEC advance is one specific arrangement rather than a disclosed total for NVIDIA’s supplier expansion.
Nor do the announced plans establish that every constraint involving wafer fabrication, high-bandwidth memory, or other advanced packaging capacity has been resolved.
The timelines reveal a gap between deployment ambitions and manufacturing capacity
The relationship between the two announcements is particularly revealing.
DSX POD deliveries are scheduled to begin in early 2027, while several major supply-chain expansions will take longer to mature. KYEC’s U.S. testing facilities target high-volume production in April 2027. Unimicron’s additional capacity is expected in the second quarter of 2027, while important substrate and advanced-packaging milestones extend into 2028.
That sequencing means the initial DSX POD deployments must rely on existing capacity and the supply available as systems are manufactured. The newly announced expansions may support subsequent growth, but they cannot automatically be credited with enabling the first shipments.
This is an important distinction when evaluating the broader strategy. NVIDIA is pursuing two complementary objectives: reducing the time required to assemble and deploy computing infrastructure, and increasing the manufacturing capacity required to supply that infrastructure over time.
The two efforts reinforce each other, but they operate on different schedules.
The practical test will be whether supplier expansions arrive on time, component yields and qualification meet requirements, and manufacturing output translates into completed systems that customers can actually deploy.
Power and cooling remain fundamental design constraints
The broader NVIDIA DSX platform also addresses how AI factories use electricity and manage heat.
Modern accelerated-computing systems concentrate substantial power consumption into dense racks. Liquid cooling transfers heat away from processors and other components, while facility-level systems must ultimately reject that heat into the surrounding environment.
NVIDIA says its DSX reference designs can use closed-loop liquid cooling and dry coolers to reduce facility cooling-water consumption by up to 100% under suitable conditions. At a hypothetical two-gigawatt deployment, the company estimates potential savings of 54 million liters of water per day compared with conventional cooling towers.
That figure concerns cooling water, not the facility’s total water footprint. Local climate also matters: extreme heat can require supplemental mechanical cooling, changing the system’s energy consumption and operating economics.
NVIDIA separately says its DSX MaxLPS software can reduce the power required to generate the same number of AI tokens by up to 30% through dynamic allocation of power within a provisioned budget.
These are potentially meaningful improvements, particularly for operators trying to maximize useful computation within fixed electrical limits. But the figures describe different outcomes and should not be combined into a single efficiency claim. Actual results will depend on workloads, system configuration, environmental conditions, and the assumptions underlying each comparison.
Reducing cooling-water demand or improving power utilization also does not create new grid capacity. Those improvements can help a facility operate more efficiently within its available resources, but they do not replace the infrastructure required to deliver electricity reliably.
Faster installation does not necessarily mean faster grid access
For the AI infrastructure industry, the distinction between equipment readiness and site readiness is becoming increasingly important.
A factory-integrated system may simplify construction and commissioning, but the facility still requires adequate electrical supply, cooling infrastructure, networking, and operational support. In markets where grid connections and permitting are already delaying projects, the limiting factor may sit outside the computing architecture altogether.
NVIDIA’s DSX Flex approach, which is intended to help AI factories adjust their power consumption to support grid operations, addresses part of that relationship between computing workloads and electricity supply. Flexible power demand can potentially help operators coordinate workloads with grid conditions.
It should not, however, be confused with a guaranteed grid connection or a substitute for transmission and generation investment.
The same distinction applies to semiconductor manufacturing. Expanding substrates, packaging, testing, and optical-engine production is strategically useful, but individual component expansions do not guarantee that every other part of the manufacturing chain will scale at the same rate.
The infrastructure challenge is systemic. Faster modules, more efficient cooling, improved power management, and greater component capacity each address part of the problem. None independently removes all the dependencies that determine how quickly a large AI computing facility can become operational.
The commercial question remains unanswered
NVIDIA’s announcements establish a direction for infrastructure development, but important commercial details remain undisclosed.
The company has not announced DSX POD pricing, a complete order book, or enough customer commitments to establish how quickly the containerized format will be adopted. Its partner ecosystem provides a potential manufacturing and delivery network, but participation in a reference design is not equivalent to a confirmed customer purchase.
The economics will depend on more than the speed of installation. Buyers will need to evaluate capital costs, transport requirements, facility integration, maintenance, hardware utilization, energy expenses, cooling performance, and the ability to expand capacity without introducing new operational constraints.
Standardization could reduce deployment variability and shorten the time before infrastructure begins generating revenue. However, those benefits must be measured against actual deployment results rather than inferred from vendor targets alone.
The first production deployments will provide important evidence about the approach’s practical limits. Useful measurements will include delivery schedules, commissioning duration, system availability, power utilization, cooling performance, and the time between equipment arrival and sustained production workloads.
Those results will help determine whether factory-built AI infrastructure becomes a widely adopted deployment model or remains best suited to a narrower set of large, well-prepared projects.
An industrial strategy, not a shortcut around physics
NVIDIA’s recent announcements signal a strategic shift toward a more integrated model for AI infrastructure. By standardizing deployable systems and incentivizing the expansion of critical manufacturing capabilities, the company aims to streamline the development lifecycle.
For operators, the potential advantages, including reduced on-site integration, greater configuration consistency, and a more predictable transition to production, are significant. However, the projected 14-day deployment timeline must be viewed as an optimization of the assembly phase, contingent upon pre-existing site readiness rather than a comprehensive timeline from project inception. Similarly, the announced supply-chain expansions represent a series of long-term milestones that, while promising, do not immediately resolve existing industry shortages.
Ultimately, the success of this initiative will depend on NVIDIA’s ability to foster a repeatable, industrialized approach to large-scale computing deployment. If executed effectively, these measures could significantly compress the infrastructure development cycle; however, the persistent bottlenecks in grid capacity, permitting, and construction remain external variables that will ultimately dictate the pace of industry expansion.